Most teams lose minutes every time someone hunts for a file.
Small, consistent indexing habits cut that time dramatically.
You don’t need a heavy taxonomy to make files findable; predictable rules and tiny metadata are enough.
This short guide outlines practical steps you can adopt today to make retrieval faster and less frustrating.
Why small indexing habits matter
When indexing is predictable, both search tools and human memory perform better, which reduces interruption time across a workday.
A few reliable touches—consistent filenames, a brief tag, and clear ownership—help files surface across platforms and search engines.
These habits prevent duplicate drafting and reduce the need to chase context from colleagues.
Over weeks and months those saved minutes accumulate into substantial productivity gains.
Small rules are easier to teach and enforce than complex taxonomies.
Start with a couple of changes and expand the practice as benefits become visible to the team.
Three lightweight metadata practices
Low-friction metadata delivers search value without heavy governance.
Pick practices that are simple to apply when creating or saving a file and that show up in search previews.
The goal is consistency: a few tokens that everyone understands and uses regularly.
These tokens make filtering and skimming results fast.
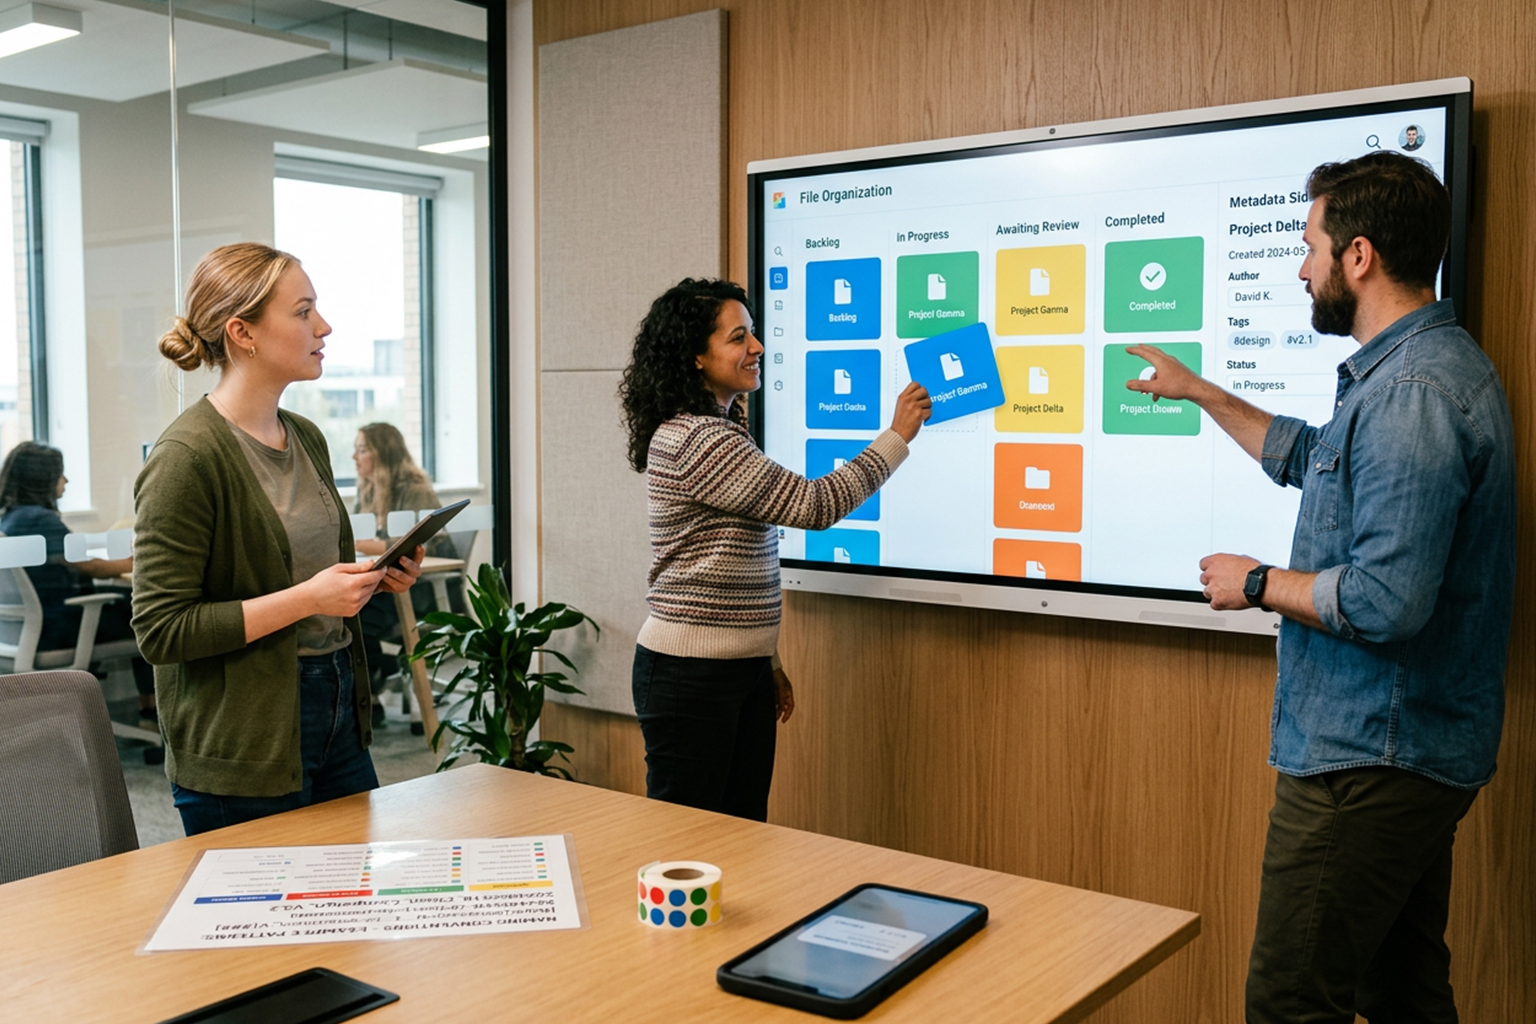
- Prefix conventions: use clear prefixes like PROJ_, TEAM_, or FIN_ so items group predictably.
- Status tags: append draft/final/review to indicate readiness without opening the document.
- Date formats: stick to YYYYMMDD or YYYY-MM to guarantee correct chronological sorting.
Keep the list short and publish examples rather than long rules.
A quick cheat sheet and a template reduce onboarding friction and improve adoption.
Design names and retention for faster discovery
Names and retention labels determine what search surfaces first, so design them with common queries in mind.
Favor natural phrases coworkers would type: project name, deliverable type, and a concise date or version.
Avoid cryptic codes unless they map to commonly known team terms, and document any exceptions.
Combine naming with straightforward retention labels so older files either archive or are flagged clearly.
Consistent naming helps autocomplete and reduces accidental duplicates.
Schedule periodic cleanups to retire stale items and keep the index relevant.
Small automations that reduce manual work
Automation removes the tedious parts of indexing and prevents human error from creeping in.
Use document templates that prefill prefixes and tags, or simple filename validators that warn on missing tokens.
Integrate these helpers into the tools your team already uses so the extra steps feel native.
Even tiny scripts that rename exports or apply retention labels can save hours at scale.
Automations should be conservative and reversible to avoid surprise changes.
Measure their impact and tweak based on real usage rather than assumptions.
Conclusion
Start with one rule that everyone can follow.
Automate where it removes friction and review results quarterly.
Small, consistent changes make file systems less painful and far easier to use.
